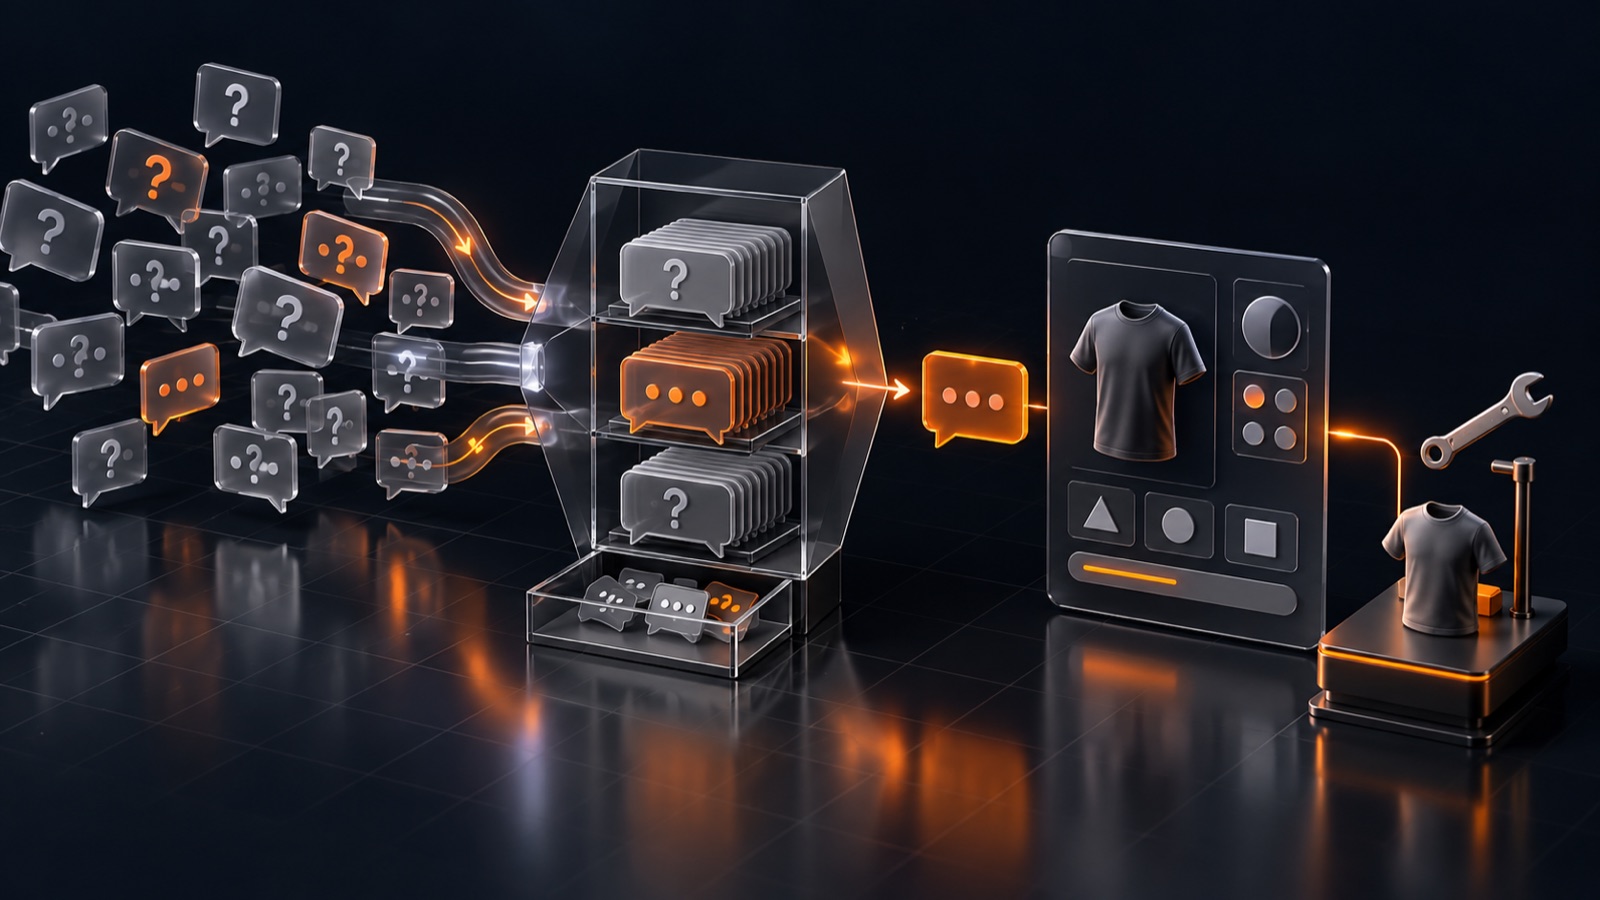
A shopper can’t tell whether a fitted sheet will fit their mattress. They check the size guide, don’t find the answer, and write to support. Support explains it. The shopper buys. The ticket closes — and from the store’s side, nothing has changed: the next shopper will hit the same wall. That gap, between a question answered and a store improved, is where AI earns its keep. Not by summarising feedback into a tidy theme, but by turning a pile of customer questions into one change a team can actually ship and test.
Separate what happened from why you think it happened
Start with the task the customer was trying to finish, not the topic they mentioned. “Choose a sheet that fits my mattress” is a task; “sizing” is just a label, and a label tells you nothing about what would make the page work.
Three shoppers can all mention fit and still need three different fixes. One can’t find the maximum mattress depth. Another sees the numbers but can’t tell which one matters. A third ordered the right size and received the wrong one. An automated summary that merges all three into “customers find sizing confusing” sounds useful and points the team nowhere — a bigger size guide will not fix a packing error.
Customer questions can show where an experience needs work. They can also mislead.
Keep the observation separate from the explanation you’re tempted to attach to it. Record what the customer said or did; propose why afterwards, and check that explanation against the actual page before you accept it. A shopper who searched the size guide and still asked about depth might be telling you the fact is missing for that variant, hidden on mobile, or absent from the translated page — not that the guide itself needs a rewrite.
Build the evidence set deliberately. Bound it to one product family, market and period. Pull in support threads, reviews, return reasons and search queries, and record what each one can and can’t tell you — a search phrase proves a question was asked, not that the person who asked it ever bought. Keep the exact wording beside the summary, especially in translation, where a smooth rewrite can quietly erase the difference between uncertainty and reported damage.
Count incidents, not just messages
Before ranking anything, agree on what you’re counting. A message, a conversation, an incident and a customer answer different questions, and conflating them inflates whatever number you want to inflate.
In a hypothetical collection, 36 support messages turn out to be only 12 distinct incidents: seven about unclear mattress-depth information, three about drying instructions, two about a packing mismatch. That is the number worth ranking — not the message count, which just tells you how much handling work the team did.
Use stable identifiers to collapse exact duplicates — the same ticket imported twice from two systems is one incident, not two. Cross-channel matches need real evidence: an order number and a continuous sequence of events can support a match; similar wording alone cannot, since two different people can ask the same question, and one person can ask it about two different orders.
Let uncertain matches stay unresolved rather than forcing a tidy total. Show how many records are still awaiting review, and check whether your ranking changes when you include them. And don’t let deduplication erase difficulty — an incident that needed three escalations deserves attention partly because of the effort it consumed, even after you’ve removed the duplicate tickets that reported it.
Give AI small, checkable jobs — then audit its work
A single prompt that says “analyse this feedback and recommend improvements” bundles several jobs into one, and when the output is wrong you can’t tell whether the model misread a message, mis-grouped an incident or invented an explanation. Split the work instead.
Extraction should return structured fields — customer task, stated difficulty, product reference, journey stage, outcome — with an explicit “unknown” where the record doesn’t say. Don’t let the model infer a product defect or a financial loss from frustrated wording alone; a complaint about fit doesn’t tell you whether the wrong size was ordered, dispatched or just described badly.
Classification needs a small taxonomy the team can explain and defend — missing specification, unclear explanation, care uncertainty, suspected fulfilment mismatch — each with a written boundary. Separate the topic (“fit”) from the cause, which should stay unknown until it is actually investigated.
Then test the classifier the way you’d test a new hire: on cases it has never seen. In one illustrative check, reviewers find 20 genuine missing-specification incidents among 50 test cases. The model flags 18; 15 are correct, three are wrong, and five real cases are missed entirely. That is roughly 83% precision and 75% recall — and the two numbers matter for different reasons. The wrong flags cost review time; the missed cases can hide a pattern nobody investigates. Reporting “only three mistakes” quietly erases the second kind of failure. Measure both, by category, before you trust the output.
Diagnose the cause, then test whether the fix worked
A count earns an investigation; it doesn’t prescribe the fix. Before touching the page, open the product variant and the version of the guide the customer actually saw. Check whether the fact is approved, present and displayed correctly on mobile as well as desktop, and watch a representative shopper attempt the task without being pointed toward the answer. If the fact itself is missing, get it from the product owner before you write a single word of copy.
A quieter support queue does not by itself prove an improved experience.
Frequency alone shouldn’t set the priority. A common question support can answer in one line deserves a quick clarification; a rarer issue that stops someone using what they already bought can outrank it. What you usually don’t know — how many silent visitors hit the same wall, how much a fix is actually worth — belongs in the brief as an open question, not as a number dressed up with false precision.
Write the fix down as something a team can finish: not “improve sizing” but “verify and display the mattress-depth limit for the affected variants, then watch whether shoppers select correctly.” Name the owner, the dependency, and the condition under which you’d roll it back.
Then test the mechanism you actually proposed. If a clearer depth limit should help shoppers choose, watch whether they now choose correctly — and if they still get it wrong, the explanation needs another look, not a louder version of itself. Where a controlled comparison is practical, define the population and the outcome before you start, and check guardrails too: a change that lifts orders but also lifts returns from unsuitable purchases hasn’t actually fixed anything.
Turning a pile of customer questions into one shipped improvement comes down to a short loop:
- Choose one customer task. Define the product family, market and decision you want to improve, and start with a collection small enough to inspect by hand.
- Preserve the original evidence. Keep record IDs, dates, product context and exact wording — and keep observation separate from interpretation.
- Define what each count means. Track message workload, distinct incidents and linked customers or orders separately, and show uncertain matches rather than forcing a clean number.
- Give AI bounded jobs. Extract, classify, retrieve and summarise with explicit fields and an “unknown” option, and require evidence behind every finding.
- Check the classifier on new cases. Measure both wrong flags and missed issues, by category, using human-reviewed examples kept apart from development.
- Verify the cause in the real journey. Inspect the actual page and product facts, watch the task, and route operational failures to the right owner.
- Write an executable brief. Name the obstacle, the proposed change, the owner, the dependency and the condition for reconsidering it.
- Test the fix and close the loop. Watch whether the task actually got easier, and tell the people answering customers what changed.
EcomExpo 2027 — 30 September, Vilnius
Turning customer questions into shipped store improvements is exactly the kind of practical AI work on the agenda when the Baltic’s largest e-commerce conference returns for its 15th edition on Thursday 30 September 2027 in Vilnius. Blind Bird tickets are €150 + VAT until 1 February 2027, before the programme is announced.
Get a Blind Bird ticket — €150Before you ship the fix: Run the free Agentic Commerce Readiness Audit — seven dimensions, 60 seconds.
EcomExpo 2027 · 15th edition · 30 September 2027 · Vilnius, Lithuania · Blind Bird €150 + VAT until 1 February 2027